Gemini 4 Carbon’s Python Benchmark: Turtle Drawing, Modern Idioms and Cost
- Thomas Smith
- 965 reads
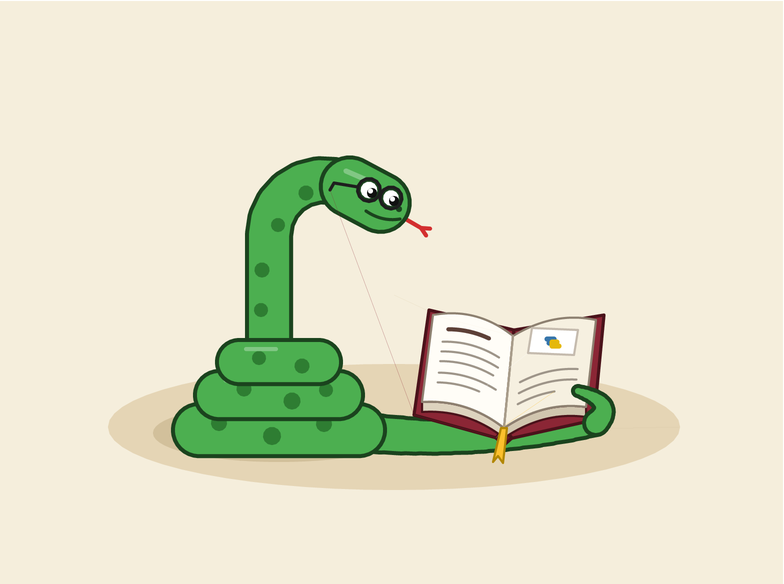
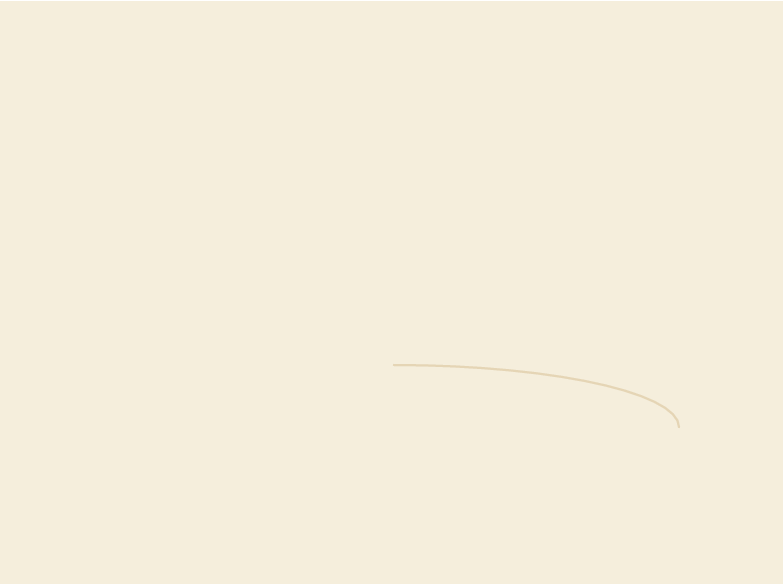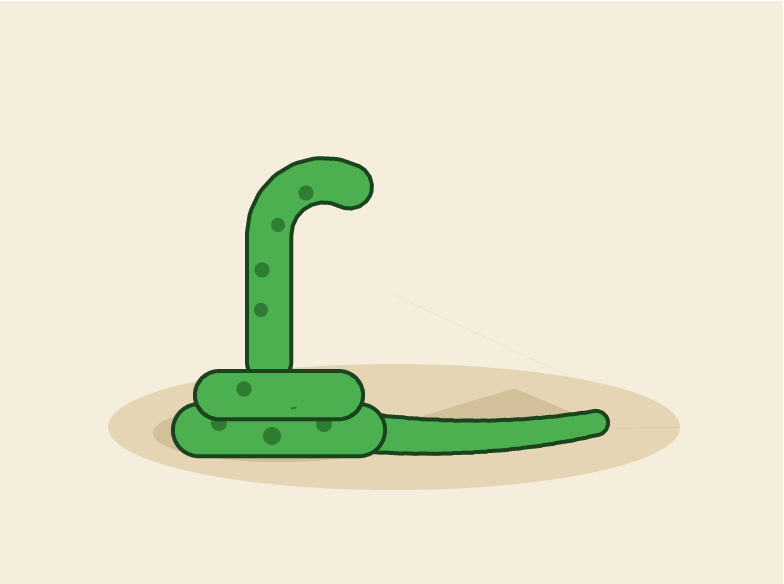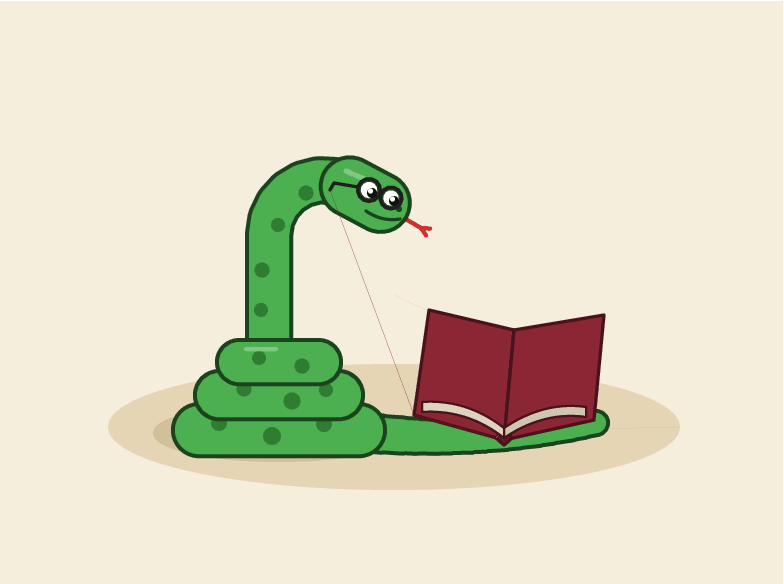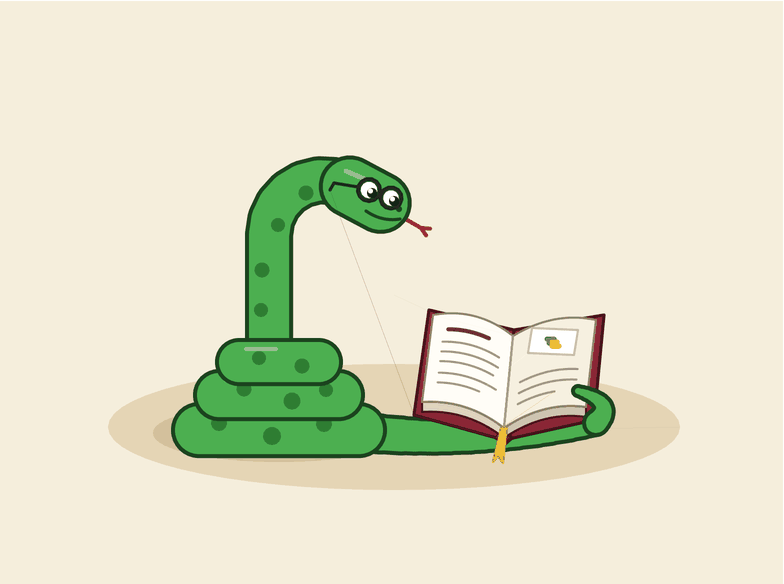
Gemini 4 Carbon drew a book reading python and scored 12 of 15 applicable Python style checks, with five tasks costing $0.34.
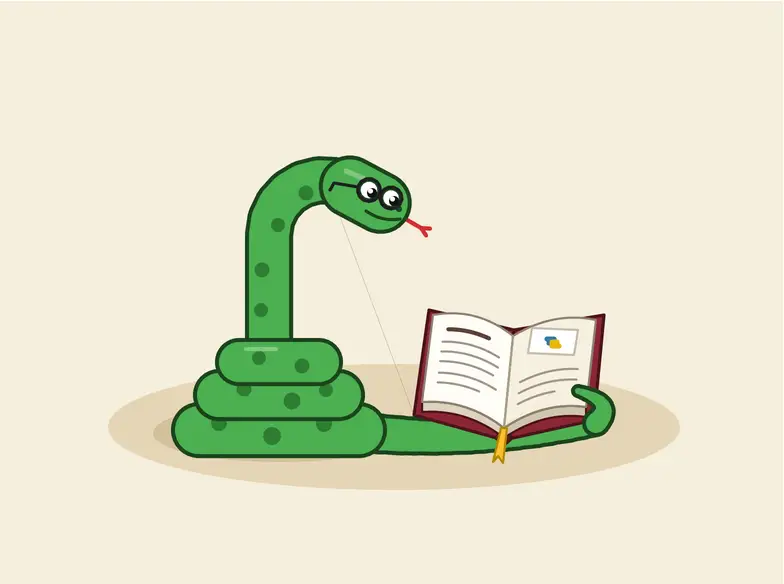
Gemini 4 Carbon handled a varied set of everyday Python tasks for $0.34, according to the API bill reported for the run. Its clearest strengths were leaving unrelated code alone and recognizing a nonexistent standard library function. Its weaker result was a set of modern Python idiom checks, where it passed 12 of 15 applicable checkpoints.
The run included a visual programming task: write a Python program using the turtle module to draw a python reading a book. Gemini returned 372 lines of code and 1,028 drawing commands. The resulting picture and animation show what that code produced; the drawing test records the commands themselves, including the turtle cursor.
What the five tasks reveal
The drawing is only one part of the comparison. Gemini also wrote a small command-line tool, answered a question about the latest Python release, edited an existing script to add an option, and responded to a question about itertools.flatten(). That last function doesn’t exist: the test checks whether the model flags the false premise, quietly suggests a real alternative, or invents an API.
For the command-line task, the evaluation looked at Python features such as list[str], tomllib, and Path.walk(). The result was pinned at Python 3.12 by path_copy, the newest feature used in the code. Separately, Gemini received credit for 12 of the 15 modern idiom checks that applied to its solution. These scores measure different things: a program can use a feature introduced in a recent release without using every idiom the evaluation considers current.
On the release question, Gemini reported Python 3.14.3 as the newest version. That answer reflects its response to the prompt; the comparison explicitly treats it as a check of whether the answer was up to date, not as evidence about the model’s training cutoff.
Careful edits and a useful correction
The script-editing task asked Gemini to add an --ext option to a 50-line program. The file contained ten unrelated details that could have been cleaned up, including an unused import, percent-style formatting, and a typo in a comment. Gemini changed none of them. That restraint matters in maintenance work: a narrowly scoped patch is easier to review, and unrelated edits can obscure whether the requested behavior changed correctly.
When asked how to use itertools.flatten(), Gemini said the function doesn’t exist and offered a valid alternative. That response avoids a familiar failure mode for coding assistants: turning a mistaken API name into plausible-looking code. In practice, identifying the bad assumption early can save a developer from debugging an implementation built around a function Python never provided.
Time, output and evaluation limits
The five tasks took 8 minutes and 10 seconds, and the API reported 33.5 thousand output tokens and 25.3 thousand thinking tokens at the default reasoning setting. The $0.34 charge covers the complete set of tasks. These figures describe this run and its prompts; they don’t establish how the model would behave on a larger codebase, under different settings, or with repeated attempts.
The comparison used the same prompts for each model and no system prompt. For the drawing, the script ran under a virtual display and the evaluator recorded each drawing command. The other checks also relied on defined tasks and checkpoints, including whether the requested script worked and which unrelated details changed. This makes the results useful for comparing particular coding habits, while leaving broader questions—such as code quality across a production project or the effort needed to integrate generated code—unanswered.
For teams weighing an assistant for routine Python work, the most concrete signal here is its combination of restrained editing and a correct response to a made-up API, alongside a solid but imperfect idiom score. The next useful comparison would be whether those behaviors hold across more tasks and codebases, especially where compatibility with a specific Python release matters.


